Psychotic KPIs
A measure can help you find out what is broken, or help you decide who to punish. Almost every organisation claims the first and practises the second. Here is why, and what to build instead.
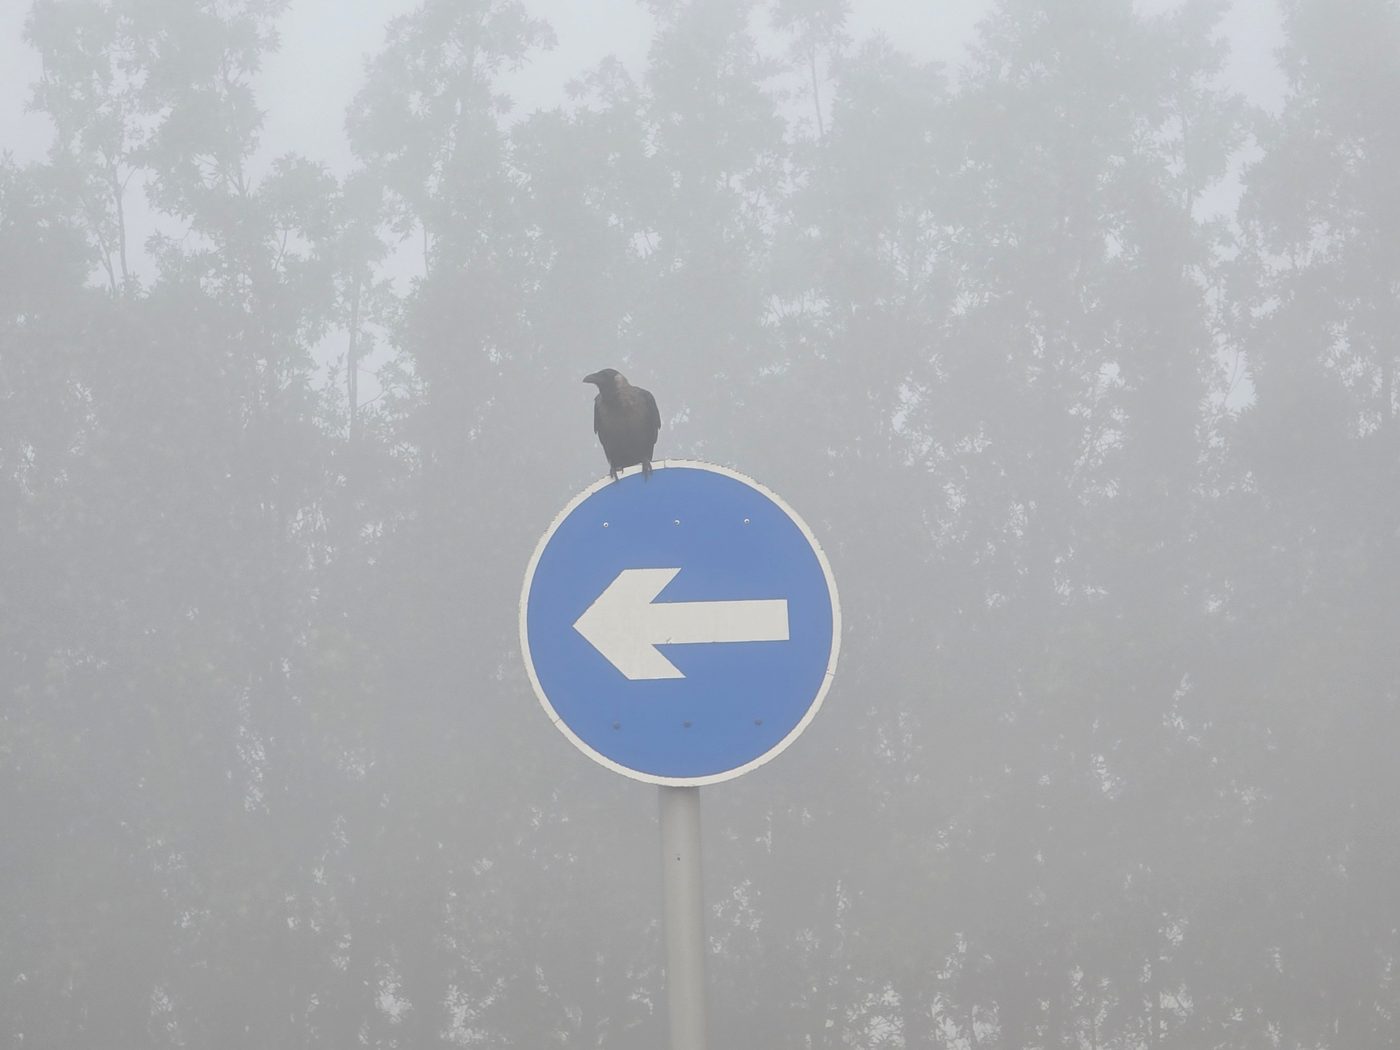
There is a crow at the top of this page, sitting on a one way sign. I took this while walking the dogs one day, because it looked like a quest marker from a CRPG. The sign points one way. The crow is under no obligation to agree with it, and neither are you.
Twenty five years dwelling and dealing with the corpocrats. Singapore, Chile, Panama, the Caribbean, and for the last several years Dubai. Government agencies, customs authorities, developers, contractors. Different languages, different industries, and the same disease everywhere, particularly in the big monolithic ones that still treat software as something you buy rather than something you build.
The failures repeat with such precision that they cannot be accidents.
Two things a KPI can be
A measure can do one of two jobs.
It can help you find out what is broken. Or it can help you decide who to punish.
A scorecard used to diagnose gets better data every year. A scorecard used to punish gets better stories every year.
Once a number carries consequences, managing the number becomes the job. Not because people are confused about the difference, but because they are not. They can see exactly where the reward sits, and they will go and stand there.
This is Goodhart's Law, best known in Marilyn Strathern's phrasing: when a measure becomes a target, it ceases to be a good measure. Donald Campbell got to the same place independently. The more a quantitative indicator is used for decision making, the more it will be corrupted, and the more it will distort the process it was meant to monitor.
The short version of the fix
Before the diagnosis, the treatment, because most people never read that far and the treatment is not complicated.
One. Every measure declares what kind of number it is. Unit type, polarity, threshold basis, precision, baseline, dependency. In a field, not a footnote.
Two. One scoring function, continuous between floor and cap, applied identically to everything. No step functions, no bespoke handling per KPI.
Three. Every stage of the build ends in an approval that freezes what came before it, so nothing can be quietly re-decided in December.
That is it. Everything below is why those three are necessary, and what happens in organisations that skip them.
I am putting the full framework together in a downloadable format below, let me ramble a bit, don't be hasty. I made it to be best used in Planner, but you do you. The murder of crows won't judge you, they may just take your eyes.
The cascade that is not a cascade
A group sits above a set of verticals. Corporate objectives get pushed down into the verticals, then into divisions, then into departments. On a slide this is drawn as a cascade, usually with chevrons.
In practice it is a photocopier.
Nobody in the middle is asked whether the measure makes sense for their business. There is no negotiation, no dependency mapping, no conversation about whether the thing being measured is even within the control of the team being measured. The target arrives, already weighted, already locked, in a spreadsheet somebody else owns.
So a development business, a sales business and a facilities business end up with structurally identical scorecards. Not similar. Identical in shape, nouns swapped, numbers changed.
Ask any division head: which of your KPIs would change behaviour if you deleted it tomorrow? In a scorecard built around how that business actually creates value, most of them. In a cascaded one, almost none.
The buzzword photocopier
There is a reason those scorecards are identical. They came from the same place, and frequently from the same slide deck.
Large organisations outsource their thinking to consultancies, then congratulate themselves on the rigour of the result. The engagement is always the same shape. A team arrives with a methodology, runs a few workshops, produces a deck, presents it to people who were never going to say no, and leaves.
That team does not know your business and has no intention of learning it, because the framework is the product. It has to be portable to be sellable, which means it has to be generic, which means it cannot possibly reflect how your tender process behaves when a drawing package lands three weeks late.
What you get instead is the slogan. One Company, One Team, One Vision. Five perspectives, customer centricity, synergy, excellence. I have watched that same slide get re-skinned and re-sold for two decades across three continents, and I have never once seen it survive contact with an actual operation.
A consultancy is paid to deliver a framework. It is not paid to operate one. Nobody who designed your scorecard will ever have to close it out.
And the organisations that keep buying this are not victims. They are customers. Paying somebody external to produce the strategy means nobody internal has to own it, and a deck with a recognised logo on the cover is very difficult to argue with in a meeting. That is not a failure of the process. For the people commissioning it, that is the process working exactly as intended.
The blame loop, and who benefits from it
Ask any division why its numbers are late and you get a coherent answer that points at somebody else.
- Tendering is late because design released the package late, and incomplete.
- Design is late because the brief changed after they started.
- The brief changed because commercial re-scoped the asset.
- Commercial re-scoped because the feasibility numbers moved.
- Feasibility moved because tendering returned prices that did not match the estimate.
A closed loop, and every account in it is locally accurate. The scorecard measures each team in isolation, so the loop is invisible to it. The organisation has a systemic delay problem and an instrument that structurally cannot see one.
I used to file this under incompetence. That was generous of me, and wrong.
A measurement system nobody can audit is not a neutral accident. It is a resource. It rewards whoever is best at narrating, best connected, and quickest to get their version of events in front of the person who decides. Those people are not confused about how the system works. They understood it before anyone else did, and they have no interest whatsoever in you fixing it.
Every unauditable system eventually grows a tribe that protects it, because the ambiguity is the point and the ambiguity is theirs.
So you get departments that optimise for looking good rather than being good, managers who spend more effort on the narrative than the delivery, and a quiet internal market in favours, exceptions and agreed adjustments. Leadership receives a permanently rosy picture and makes confident decisions on the back of it, which is how organisations walk into walls at speed while every line on the board pack is green.
None of this requires a conspiracy. It only requires ordinary self interest and a system with no defence against it.
Four ways a scorecard goes psychotic
The mechanics. Clean invented numbers so the mechanism is visible.
1. The cliff
A measure has a target of 100 units and a minimum threshold at 95 percent. Below the floor, the rule says zero.
| Achieved | Shortfall | Score under a step rule |
|---|---|---|
| 95 units | 5% | Full weight earned |
| 94 units | 6% | Zero |
One unit of performance is worth the entire weighting of the line. Performance moves continuously, score moves in a step. Cliffs do two things.
They concentrate all managerial attention at the boundary. At 96 you defend it with everything you have. At 80 in November you have no reason to reach 90, because 90 pays the same as 80, which is nothing.
And they are unenforceable. When a large, visible measure lands just under the floor, no organisation accepts a zero on its flagship line. A pro rata calculation appears, or an adjustment is agreed, or a footnote arrives. At that moment you have established that the rule is negotiable, which means you no longer have a rule.
2. The moving goalpost and the swapped ruler
Two versions of the same trick.
A target is set in January. By September it is clear the year will fall short, so the target is revised down. Against the original it is a miss. Against the revision it is comfortably above expectation.
Or the target holds and the baseline moves instead. A milestone measure defined against contractual dates gets assessed against business plan dates at close out, which are more forgiving, and the measure lands above target.
Sometimes a revision is genuinely justified. That is not the problem. The problem is a change that is neither versioned nor dated nor attributed, so the published score cannot be reproduced by anyone who was not in the room.
If your baseline can be substituted after you know the result, your baseline is not a baseline. It is a preference.
3. Measuring noise
A satisfaction measure carries a ten percent weighting, scored on a band from 6.9 to 7.2 on a ten point survey.
That band is 0.3 wide. Now ask what the sampling error is. If it is plus or minus 0.4, and on most internal surveys it is worse, then ten percent of a board level scorecard is being decided by statistical noise. Rerun the identical survey on the identical population and you score differently.
If the scoring band is narrower than the error of the instrument, you are not measuring performance. You are measuring the survey.
4. The cap that hides a broken target
Most scorecards cap achievement at 110 percent, which is sensible on its own. It stops one runaway line carrying the whole card.
But watch what it conceals. One measure has a target of 10 and delivers 28. Another has a target of 100 and delivers 110. Both hit the cap. Both score identically.
The first is not excellence, it is a broken target, and it is telling you something important about how this organisation sets numbers. The cap swallows that signal every year and nobody investigates, because the line is green.
The one that causes all the others: nothing is normalised
If I could fix one thing only, it would not be any of the four above. It would be this, because it is what makes the others possible.
Open any scorecard workbook and read down a single column. Call it Minimum Threshold.
| KPI | Threshold value | What it actually means |
|---|---|---|
| Sales | 0.95 | 95 percent of target, a ratio |
| Customer satisfaction | 6.7 | An absolute score on a ten point scale |
| Brand awareness | 40% | 40 percentage points in absolute terms, not 40 percent of target |
| Cost variance | -5% | A signed deviation, where lower is better |
Four rows, four different units of meaning, one column. Distinguished by a footnote and somebody's memory of a conversation in March.
A column that needs a footnote to explain its own meaning has failed as a schema. Two competent analysts will compute different scores from the same file and both will be right according to their reading. That is not a disagreement about performance, it is a disagreement about arithmetic, and it is entirely self inflicted.
The same disease runs through the target column, where a percentage target might mean growth on last year, or an absolute rate, or a share of a total, with nothing in the file to say which. And through polarity, where nowhere is it written whether a measure should go up or down. Obvious for revenue. Obvious in reverse for cycle time. Not obvious at all for variance to plan, and I have watched two teams build the same measure with opposite signs and argue about it for a fortnight.
If a column cannot be read without a conversation, it is not data. It is a rumour with formatting.
What normalising actually means
Not forcing everything onto one scale. Some things are percentages, some are counts, some are dates, some are survey scores. You cannot flatten that and you should not try.
It means every number declares what kind of number it is. Once each measure carries its own type, the ambiguity disappears and nobody has to remember anything.
| Declared field | Allowed values | The ambiguity it kills |
|---|---|---|
| Unit type | ratio, absolute, currency, count, days, index, score | Is 0.95 a ratio or a value? |
| Threshold basis | percent of target, or absolute | One column carrying four meanings |
| Polarity | higher is better, lower is better | Direction guessed from the KPI's name |
| Target type | static, or variable across the period | Interval targets that cannot be expressed |
| Precision | the instrument's margin of error | Scoring bands narrower than survey error |
| Baseline | comparison basis, locked at cycle start | Rulers swapped after the result is known |
| Dependency | external teams named at definition | Blame loops and close out attribution fights |
Seven fields. No tool required, no platform, no consultant. Somebody sits down before the cycle opens and writes down what they meant.
And here is the payoff. Once every measure declares its unit type and polarity, the scoring function can be generic. You stop writing a bespoke calculation for each KPI with its own special handling and its own footnote, and start running one function over a properly typed register. That is the difference between a scorecard you can audit and a scorecard you have to interview.
One function, not a step
Replace the cliff with a bounded, continuous conversion. Same floor, same cap, same weights. Performance between floor and target earns proportionally, so improvement is always worth something.
On a target of 100, a floor at 80, a cap at 110, and a delivery of 94:
| Model | Calculation | Weight earned | Reproducible? |
|---|---|---|---|
| Step, floor at 95 | 94 is below the floor | 0 of 10 | Only until somebody objects |
| Bounded linear, floor at 80 | [94 − 80] ÷ [100 − 80] = 70% | 7.0 of 10 | Yes, by anyone |
Note what this does not do. It does not lower the target, raise the cap or soften accountability. A material miss still carries a material consequence. It removes the discontinuity that made the rule unenforceable, and therefore negotiable.
One exception that matters. Genuine pre-qualifiers stay binary. Safety, regulatory compliance, audit closure. Those are obligations, not continuous measures, and a knock out treatment is correct.
The lifecycle, with gates
This is the framework I came up with one day, as usual while walking the dogs and talking to crows. Here it is because I built it, and open source this and that always, you know? bazaars before cathedrals and because we, proletarians, should unite and so on. Feel free to use it, change it or destroy it.
Six buckets in order. Each holds five tasks, each task holds five checklist items. Thirty tasks and one hundred and fifty checklist items, which sounds like a lot until you notice most of them are things you were going to have to decide anyway, just later and under worse conditions.
| # | Bucket | The question it answers | Closes with |
|---|---|---|---|
| 01 | Business context and KPIs | What are we measuring, how is it measured, what are the targets and who owns them? | Approve KPI Register |
| 02 | Data points | What fields, measures, dimensions and business rules does that require? | Approve Data Requirements |
| 03 | Data sources | Where does each number come from, who owns it, how good is it? | Approve Source Register |
| 04 | Data engineering | Can it be extracted, transformed and validated repeatably? | Approve Data Engineering Output |
| 05 | Analytics and insights | Are the measures built, reconciled and turned into something a human can act on? | Approve Insight Pack |
| 06 | Reporting and visualisation | Is the output built, validated, published and running on a cycle? | Establish Reporting Cycle |
The template, free to take
All six buckets, thirty tasks and one hundred and fifty checklist items, in one workbook. No signup, no email, no licence. Use it, fork it, argue with it, hate it.
Two rules that make it work
Rule one: every task ends with an artefact
The fifth checklist item on all thirty tasks is the same instruction. Create or link the artefact. Stakeholder and objectives artefact, KPI register, ownership artefact, business rules, source register, ETL approach, data model, insight catalogue, and so on.
The board tracks method and progress. The content lives in the artefact. The moment you start storing KPI definitions inside your tracking tool, you have rebuilt the problem you were escaping.
If the definition of a KPI lives in the same cell as the status of the task to define it, you do not have a framework. You have a to do list with opinions.
Rule two: every bucket ends with an approval
Bucket 01 does not finish when somebody has drafted some KPIs. It finishes at 01.05 Approve KPI Register, its own task with its own checklist: review the register, review targets and ownership, resolve open comments, obtain approval, link the approved artefact.
That gate is where most of the damage gets prevented.
| The defect | What stops it |
|---|---|
| The cliff | 01.02 forces methodology, targets and thresholds to be defined together, before anything is built. The scoring function becomes a design decision rather than a December improvisation. |
| The moving goalpost and the swapped ruler | 01.05 locks the register. A target or baseline can still change, but it changes by going back through an approval gate, which means versioned and attributed rather than quietly edited. |
| Measuring noise | 01.02 validate the KPI set, plus 03.03 assess source quality, completeness and availability. If the instrument cannot support the band, you find out in bucket 03, not in the board pack. |
| Nothing normalised | 02.02 identify measures, dimensions and attributes, then 02.03 define business rules split into inclusion, exclusion and classification. Unit type and polarity become declared properties instead of things inferred from a heading. |
| The blame loop | 01.03 names KPI owners, data owners, review authority and approval authority as four separate things. 03.02 forces alignment with source owners up front. Dependencies get declared at definition instead of discovered during an argument. |
None of that is clever. It is deciding things in advance, writing them down, and getting somebody to sign the version you decided.
One more piece people skip. Bucket 06 does not end when the dashboard is published. 06.04 publishes it. 06.05 establishes the reporting cycle: refresh cycle, review cycle, update responsibilities, issue management. That is the difference between a report and a running system. Most of the scorecards I have been asked to fix had no equivalent of 06.05. Built once, published once, then maintained by whoever still had the file.
The only test that matters
Two competent people, given the same data and the same published rules, must arrive at the same score without speaking to each other.
If they cannot, then whatever produced your number was not a calculation. It was a negotiation wearing a calculation's clothes, and the figure at the top of the deck describes the meeting more accurately than it describes the business.
Which is why the conversation in the room always feels slightly unreal. Everyone is discussing an agreement and calling it a measurement.
The sign says one way. The crow is still not obliged to agree with it.
Recognise any of this?
Most organisations have at least two of these sitting in a workbook right now, usually without knowing it. If you are rebuilding a scorecard, defining KPIs for a new cycle, or just want to argue with me about threshold design, I am happy to talk.
Get in touchSources and further reading
None of the underlying arguments are original to me. If you are making this case internally, these are worth citing.
-
Goodhart, C. / Strathern, M.. Goodhart's Law and its best known restatement, when a measure becomes a target, it ceases to be a good measure. Summary and provenance held by the University of Cambridge.
damtp.cam.ac.uk/user/mem/papers/LHCE/goodhart.html -
Bevan, G. and Hood, C. [2006], What's Measured Is What Matters: Targets and Gaming in the English Public Health Care System, Public Administration 84[3], 517–538. The definitive study of targets, gaming and measurement failure under a published scoring regime.
researchonline.lse.ac.uk/id/eprint/16211 -
Courty, P. and Marschke, G. [2004], An Empirical Investigation of Gaming Responses to Explicit Performance Incentives, Journal of Labor Economics 22[1]. Shows that strategic timing and reporting under nonlinear awards causes real efficiency loss, not merely accounting noise.
jstor.org/stable/10.1086/380402 -
Owan, H., Tsuru, T. and Uehara, K. [2015], Incentives and Gaming in a Nonlinear Compensation Scheme, Evidence-based HRM 3[3], 222–243. Agents adjust effort to their position in the pay schedule and game the scheme where the marginal return is high.
emerald.com/ebhrm/article/3/3/222 -
Grant, D.. The Essential Economics of Threshold-Based Incentives. Why the marginal benefit of improvement falls to nil unless a threshold is crossed, and why incentive effects vary discontinuously near the boundary.
sole-jole.org/assets/docs/15037.pdf -
Van Dooren, W., Bouckaert, G. and Halligan, J.. Performance Management in the Public Sector, Routledge. Distinguishes functional from dysfunctional effects of measurement, including ratchet effects, tunnel vision and goal displacement.
taylorfrancis.com -
Awadallah, E. and Allam, A. [2015], A Critique of the Balanced Scorecard as a Performance Measurement Tool, International Journal of Business and Social Science 6[7]. On the limitations in concept, application and practice that lead to abandonment.
ijbss.thebrpi.org